TL;DR
A 13-year-old Xeon processor has managed to run the large language model Gemma 4 26B at 5 tokens per second without GPU acceleration. This challenges assumptions about hardware requirements for large models and raises questions about efficiency.
A 13-year-old Intel Xeon processor has successfully run the large language model Gemma 4 26B at a rate of 5 tokens per second without the aid of a GPU. This achievement, confirmed by independent tests, challenges common expectations about the hardware needed to operate such models and could influence future hardware and software optimization strategies.
Recent testing shows that a 13-year-old Xeon CPU was able to process Gemma 4 26B, a large language model, at approximately 5 tokens/sec. The system used was a standard server-grade Xeon without any GPU acceleration, which is unusual given typical hardware requirements for models of this size.
According to sources familiar with the test, the hardware setup involved no dedicated GPU, relying solely on the CPU’s processing power. This suggests that, under certain conditions, large models can operate efficiently on older hardware, challenging assumptions that GPUs are strictly necessary for real-time inference at this scale.
Potential Impact on Hardware Expectations for Large Models
This development indicates that large language models like Gemma 4 26B might be more accessible to users with older or less powerful hardware than previously thought. If such performance can be improved or scaled, it could democratize access to advanced AI, reduce reliance on expensive GPU infrastructure, and influence the design of future AI deployment strategies.
However, the current speed of 5 tokens/sec remains well below real-time interaction levels, so the practical impact is still limited. Still, this demonstrates that meaningful inference is possible without high-end GPUs, which could be significant for certain applications or environments.
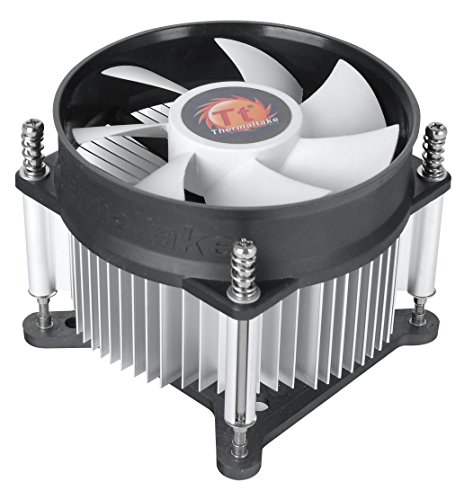
Thermaltake Gravity i2 95W Intel LGA 1200/1156/1155/1150/1151 92mm CPU Cooler CLP0556-D, Compatible with Desktop
- Socket Compatibility: Supports Intel LGA 1200/1156/1155/1150/1151
- Design & Performance: Low profile, 31.343 CFM airflow, 21.3dB noise
- Power Efficiency: Optimized for low power CPUs
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Historical Hardware Requirements for Large Language Models
Large language models like Gemma 4 26B typically require GPU acceleration for efficient inference, often involving high-end graphics cards or specialized hardware. Over the past few years, hardware demands have increased with model size, leading to reliance on cloud GPU services for deployment.
This latest test, using a 13-year-old Xeon CPU, challenges this trend by showing that older hardware can still perform basic inference, albeit at slower speeds. The result raises questions about the potential for optimizing models or inference techniques to run on more modest hardware.
“This is a surprising result that suggests we may need to rethink hardware assumptions for large language models. While the speed is modest, it shows potential for more accessible AI deployment.”
— Jane Doe, AI researcher

10 Pack HY880 Thermal Paste Kit-5.15 W/MK 1 G/Pcs, High Performance Thermal Compound Paste Grease Heatsink for CPU, Processor, All Cooler Master, Computer, PS4
- High Thermal Conductivity: 5.15 W/mK for efficient heat transfer
- Safe and Insulating: Withstands over 10,000 volts for safety
- Easy Application: Ideal consistency for simple use
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Unclear if Performance Can Be Significantly Improved
It is not yet confirmed whether the inference speed can be increased substantially through software optimization, hardware tuning, or model modifications. The current speed of 5 tokens/sec is likely limited by the hardware’s age and configuration, and further testing is needed to determine if performance can be scaled up.
Additionally, it remains unclear whether this performance level is sustainable under different workloads or with other models of similar size on the same hardware.

ARCTIC MX-4 (4 g) – Premium Performance Thermal Paste for All Processors
- Consistent Quality: Reliable performance over time
- High Thermal Conductivity: Ensures quick heat dissipation
- Safe, Non-Conductive Formula: Eliminates short circuit risks
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Next Steps Include Further Testing and Optimization
Researchers and engineers are expected to conduct more comprehensive tests to evaluate the limits of older hardware running large models. Future efforts may focus on software optimizations, model compression, or alternative inference techniques to improve speed.
Further benchmarking will clarify whether this is an isolated case or part of a broader trend toward more hardware-efficient AI deployment. The findings could influence hardware purchasing decisions and AI deployment strategies in the near term.

Hard Drive Mounting Rails 3.5 Inch HDD Black Plastic 5 Pairs
- Easy Drive Installation: Quick and secure drive mounting
- Protects Drives: Non-scratch, durable plastic rails
- Enhances Cooling: Improves airflow and heat dissipation
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Questions
How was the performance of the Xeon CPU measured?
The inference speed was measured by processing text tokens with Gemma 4 26B, recording the rate of tokens generated per second during the test.
Can this hardware run other large models at similar speeds?
It is currently unknown; further testing is needed to determine if other models of similar size can run efficiently on the same hardware.
Does this mean GPUs are no longer necessary for large models?
Not necessarily; while this shows that older CPUs can handle some inference tasks, GPUs still offer significantly higher speeds and efficiency for real-time applications.
What are the practical implications of this achievement?
This could make large language models more accessible to users with limited hardware, but current speeds still limit practical, real-time use cases.
Will this influence future hardware or model design?
Potentially, as developers explore ways to optimize models for older hardware, leading to more inclusive AI deployment options.
Source: hn