TL;DR

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
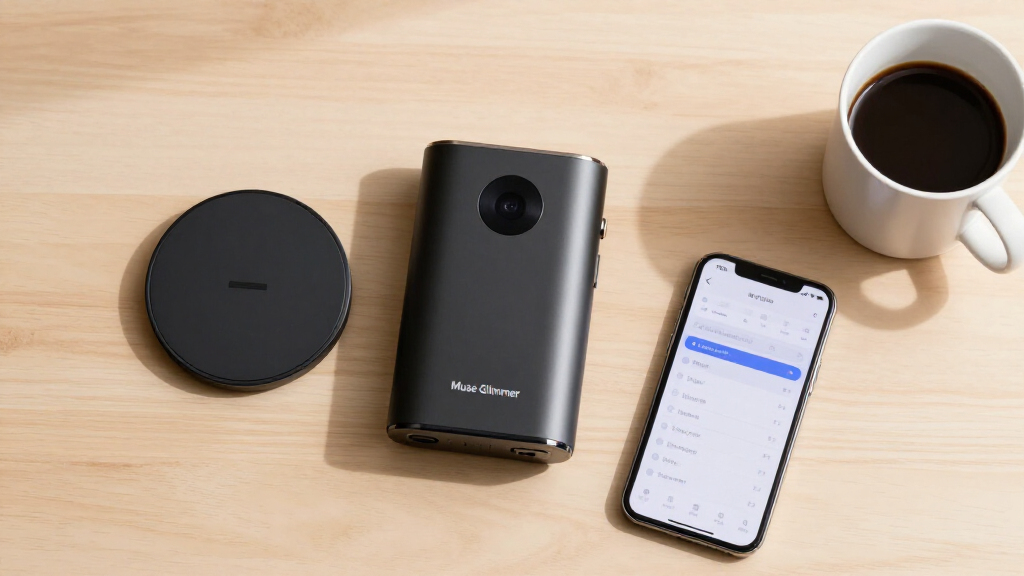
Muse has released Glimmer, a 30-billion-parameter AI model designed specifically for always-on local agent applications. This development aims to improve real-time responsiveness and data privacy in embedded AI systems, marking a significant step in local AI deployment.
Muse has unveiled Glimmer, a 30-billion-parameter AI model specifically optimized for always-on local agent workflows. This development targets applications requiring continuous, real-time AI processing on local devices, emphasizing privacy and responsiveness. The release aims to address growing demand for embedded AI solutions that do not rely on cloud connectivity.
Muse’s Glimmer is a large language model with 30 billion parameters, designed to operate effectively in persistent, local environments. According to Muse, the model is optimized for low-latency, always-on workflows, making it suitable for embedded systems, edge devices, and enterprise applications where continuous AI operation is critical. The company states that Glimmer can perform complex tasks such as real-time decision-making, natural language understanding, and contextual responses without needing cloud access. Muse highlighted that Glimmer’s architecture emphasizes efficiency, allowing it to run on hardware with limited resources while maintaining high performance. The model has been fine-tuned for local agent scenarios, including smart devices, industrial automation, and privacy-sensitive applications. Muse has not disclosed specific technical benchmarks but claims that Glimmer offers a balance between size, speed, and accuracy comparable to larger models running in cloud environments. The company also emphasizes that the model supports continuous learning and adaptation in local contexts, although details about update mechanisms remain unspecified.Implications for Embedded AI and Privacy
The release of Muse’s Glimmer marks a notable advancement in local AI deployment, enabling real-time, always-on processing on edge devices. This can significantly enhance privacy, as data remains on local hardware, and reduce latency issues associated with cloud-based AI. Industries such as smart homes, industrial automation, and autonomous systems stand to benefit from this development, as they require reliable, low-latency AI capabilities. The move also signals a shift toward more capable, self-sufficient AI models that do not depend on constant cloud connectivity, potentially transforming how AI is integrated into everyday devices and enterprise systems.edge AI hardware for local AI models
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Growing Demand for Local, Always-On AI Solutions
Over recent years, there has been increasing demand for AI models capable of operating locally, driven by privacy concerns, latency requirements, and the desire for autonomous operation. Major tech companies and startups alike have invested in edge AI hardware and models tailored for persistent, offline use cases. Prior to Glimmer, most large language models required cloud-based processing, limiting their suitability for real-time, privacy-sensitive applications. Muse’s entry with a 30-billion-parameter model optimized for local workflows aligns with this trend, filling a gap for high-capacity models that can run efficiently on constrained hardware. While several smaller models exist for edge deployment, Glimmer’s size and claimed performance suggest a significant step forward in local AI capabilities.“Glimmer is designed to bring high-performance AI directly to local devices, enabling continuous, real-time workflows without compromising privacy.”
— Muse spokesperson
As an affiliate, we earn on qualifying purchases.
Technical Performance and Deployment Details Still Unclear
It is not yet confirmed how Glimmer’s performance compares in real-world benchmarks against existing models, nor what hardware specifications are required for optimal operation. Details about update mechanisms, training data, and long-term adaptability remain undisclosed, leaving questions about its scalability and integration in various environments.As an affiliate, we earn on qualifying purchases.
Upcoming Deployment and Benchmarking Opportunities
Muse is expected to release technical benchmarks and detailed hardware requirements soon, providing clearer insights into Glimmer’s performance. The company may also announce pilot programs or partnerships with device manufacturers to demonstrate real-world applications. Observers will be watching for updates on how well Glimmer performs in different edge scenarios and whether it can support continuous learning in live environments.As an affiliate, we earn on qualifying purchases.
Key Questions
What makes Glimmer different from other AI models?
Glimmer is a 30-billion-parameter model optimized specifically for always-on, local workflows, emphasizing low latency, privacy, and efficiency in embedded systems.
Can Glimmer run on typical consumer hardware?
While specific hardware requirements are not yet detailed, Muse claims Glimmer is designed to operate efficiently on hardware with limited resources, making it suitable for edge devices and embedded systems.
Will Glimmer support real-time learning or updates?
Muse has indicated that Glimmer supports continuous adaptation, but details about its update mechanisms or online learning capabilities have not been disclosed.
When will technical benchmarks for Glimmer be available?
Muse is expected to release benchmarking data and hardware specifications soon, which will clarify Glimmer’s performance in various deployment scenarios.
What industries are most likely to benefit from Glimmer?
Industries such as smart home automation, industrial IoT, autonomous vehicles, and privacy-sensitive enterprise applications are prime candidates for deploying Glimmer.
Source: hn
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.